Stable Diffusion
| Model | Source | Revision | Weight license | Parity (CPU, fp32) |
|---|---|---|---|---|
sd-v1-1 |
CompVis/stable-diffusion-v1-1 | 574555a |
CreativeML-OpenRAIL-M | Verified |
sd-v1-2 |
CompVis/stable-diffusion-v1-2 | f519eeb |
CreativeML-OpenRAIL-M | Verified |
sd-v1-3 |
CompVis/stable-diffusion-v1-3 | 159f26f |
CreativeML-OpenRAIL-M | Verified |
sd-v1-4 |
CompVis/stable-diffusion-v1-4 | 133a221 |
CreativeML-OpenRAIL-M | Verified |
sd-v1-5 |
stable-diffusion-v1-5/stable-diffusion-v1-5 | 451f4fe |
CreativeML-OpenRAIL-M | Verified |
dreamshaper-8 |
Lykon/dreamshaper-8 | a7e52b9 |
CreativeML-OpenRAIL-M | Verified |
sdxs-512-0.9 |
IDKiro/sdxs-512-0.9 | c332f05 |
CreativeML-OpenRAIL++-M | Verified |
segmind-small-sd |
segmind/small-sd | f8b087e |
CreativeML-OpenRAIL-M | Verified |
segmind-tiny-sd |
segmind/tiny-sd | cad0bd7 |
CreativeML-OpenRAIL-M | Verified |
bk-sdm-base |
nota-ai/bk-sdm-base | 0c03b7a |
CreativeML-OpenRAIL-M | Verified |
bk-sdm-small |
nota-ai/bk-sdm-small | 572238d |
CreativeML-OpenRAIL-M | Verified |
bk-sdm-tiny |
nota-ai/bk-sdm-tiny | 0364108 |
CreativeML-OpenRAIL-M | Verified |
bk-sdm-v2-base |
nota-ai/bk-sdm-v2-base | 21915be |
CreativeML-OpenRAIL-M | Verified |
bk-sdm-v2-small |
nota-ai/bk-sdm-v2-small | ad82c51 |
CreativeML-OpenRAIL-M | Verified |
bk-sdm-v2-tiny |
nota-ai/bk-sdm-v2-tiny | 68277af |
CreativeML-OpenRAIL-M | Verified |
lcm-dreamshaper-v7 |
SimianLuo/LCM_Dreamshaper_v7 | a85df6a |
MIT | Verified |
sd-v2-1 |
sd2-community/stable-diffusion-2-1 | bb21548 |
CreativeML-OpenRAIL++-M | Verified |
sd-turbo |
stabilityai/sd-turbo | b261bac |
sai-nc-community | Verified |
Stable Diffusion 1.x
Catalog: stable-diffusion-1 ·
Models: sd-v1-1 … sd-v1-5, dreamshaper-8 · Task: t2i
Architecture. An f=8 KL autoencoder (512×512×3 image ↔ 64×64×4 latent), a 860M-parameter U-Net
conditioned through cross-attention, and a frozen CLIP ViT-L/14 text encoder (last layer, unpooled
output). The base checkpoints use PNDM (skip_prk_steps=True, i.e. PLMS); DreamShaper 8 uses the
published second-order DEIS scheduler.
Usage.
python -m imagehub.pretrained sd-v1-5 checkpoints/sd-v1-5
python -m imagehub.pretrained dreamshaper-8 checkpoints/dreamshaper-8
from imagehub import pipeline

with pipeline("t2i", backend="sd-v1-5", model="checkpoints/sd-v1-5", device="mps") as pipe:
    result = pipe("a cat, oil painting", seed=42, negative_prompt="blurry")
    result.images[0].save("cat.png")
Settings. steps (50), guidance (7.5; 1 and below turns guidance off), width/height
(512, multiples of 8), negative_prompt, num_images (1), seed, latents. Unrecognized settings
raise an error.
Select backend="dreamshaper-8" with model="checkpoints/dreamshaper-8" to use the fine-tune.
Seed compatibility. On CPU, the same seed gives the same image as diffusers with
generator=torch.Generator("cpu").manual_seed(seed) (validation). MPS has a smoke
test (at most 1 pixel of difference from CPU, PSNR 72.8 dB); CUDA has not been tested yet. There is
no claim of exact equality on these devices.
Out of scope. There is no safety checker or invisible watermark. img2img, other schedulers and fp16 parity are not in this release.
License. The weights are licensed under CreativeML OpenRAIL-M; the license's use restrictions bind whoever downloads and uses the weights. imagehub does not distribute weights.
SDXS-512
Catalog: sdxs ·
Model: sdxs-512-0.9 · Task: t2i
Architecture. SDXS-512 is a one-step distilled Stable Diffusion model. It uses a three-stage, one-layer U-Net without a mid block, an OpenCLIP ViT-H/14 text encoder, a tiny distilled autoencoder, and the published Euler scheduler with trailing timestep spacing.
Usage.
from imagehub import pipeline

with pipeline("t2i", backend="sdxs-512-0.9", model="checkpoints/sdxs-512-0.9") as pipe:
    result = pipe("portrait photo of a girl, golden hour", seed=42)
    result.images[0].save("portrait.png")
Settings. The model-card defaults are steps=1 and guidance=0.0. Output defaults to
512×512; width and height must be multiples of 8. negative_prompt, num_images, seed, and
latents are also accepted. Unrecognized settings raise an error.
Out of scope. There is no safety checker or invisible watermark. Image conditioning, img2img, the optional large VAE, alternate schedulers, and fp16 parity are not included.
License. The weights use CreativeML Open RAIL++-M. Its use restrictions bind whoever downloads and uses the weights; imagehub does not distribute weights.
Segmind Small-SD and Tiny-SD
Catalog: bk-sdm ·
Models: segmind-small-sd, segmind-tiny-sd · Task: t2i
Architecture. These are knowledge-distilled Stable Diffusion 1.x checkpoints with pruned U-Nets. Small-SD keeps four channel stages but one residual/attention layer per stage. Tiny-SD keeps three stages and removes the mid-block. They retain the CLIP text encoder and f=8 KL autoencoder layout. Small uses its published second-order DEIS scheduler; Tiny uses its published second-order DPM-Solver++ scheduler.
Usage.
python -m imagehub.pretrained segmind-small-sd checkpoints/segmind-small-sd
python -m imagehub.pretrained segmind-tiny-sd checkpoints/segmind-tiny-sd
from imagehub import pipeline

with pipeline(
    "t2i", backend="segmind-tiny-sd", model="checkpoints/segmind-tiny-sd"
) as pipe:
    result = pipe("a cat, oil painting", seed=42)
    result.images[0].save("cat.png")
Settings. steps (50), guidance (7.5), width/height (512, multiples of 8),
negative_prompt, num_images, seed, and latents. Unrecognized settings raise an error.
Tiny-SD publishes only float16 weights; CPU validation upcasts them to float32.
Out of scope. There is no safety checker or invisible watermark. img2img and alternate schedulers are not included.
License. Both weight sets use CreativeML OpenRAIL-M. Its use restrictions bind whoever downloads and uses the weights; imagehub does not distribute weights.
BK-SDM
Catalog: bk-sdm ·
Models: bk-sdm-base, bk-sdm-small, bk-sdm-tiny, bk-sdm-v2-base,
bk-sdm-v2-small, bk-sdm-v2-tiny · Task: t2i
Architecture. BK-SDM distills Stable Diffusion 1.4 into smaller U-Nets by removing repeated residual and cross-attention blocks. Base keeps four stages and the cross-attention mid block; Small removes the mid block; Tiny also removes the innermost stage. All three reuse the SD 1.4 CLIP text encoder, f=8 KL autoencoder and PNDM scheduler.
The v2 checkpoints apply the same three pruning layouts to Stable Diffusion 2.1-base. They use its 23-layer OpenCLIP-H text encoder, 1024-wide text conditioning and linear-projection U-Net attention, while retaining the published epsilon-prediction PNDM scheduler and 512×512 native image size.
Usage.
python -m imagehub.pretrained bk-sdm-small checkpoints/bk-sdm-small
python -m imagehub.pretrained bk-sdm-v2-small checkpoints/bk-sdm-v2-small
from imagehub import pipeline

with pipeline("t2i", backend="bk-sdm-v2-small", model="checkpoints/bk-sdm-v2-small") as pipe:
    result = pipe("a cat, oil painting", seed=42, negative_prompt="blurry")
    result.images[0].save("cat.png")
Settings. steps (50), guidance (7.5; 1 and below turns guidance off), width/height
(512, multiples of 8), negative_prompt, num_images (1), seed, latents. Unrecognized settings
raise an error.
Out of scope. There is no safety checker. Image-to-image, DreamBooth training, 2M-data variants, Core ML exports and fp16 parity are not included.
License. The weights are licensed under CreativeML OpenRAIL-M; its use restrictions bind whoever downloads or uses them. imagehub does not distribute weights.
Latent Consistency Model (LCM)
Catalog: lcm ·
Models: lcm-dreamshaper-v7 · Task: t2i
Architecture. A Stable Diffusion 1.x architecture distilled with latent consistency. Guidance enters the U-Net as an embedding instead of classifier-free guidance. The checkpoint uses an LCM scheduler and has a native image size of 768×768.
Usage.
from imagehub import pipeline

with pipeline(
    "t2i", backend="lcm-dreamshaper-v7", model="checkpoints/lcm-dreamshaper-v7", device="mps"
) as pipe:
    result = pipe("a cat, oil painting", seed=42)
    result.images[0].save("cat.png")
Settings. steps defaults to 4, guidance defaults to 8.0 and width/height default to
768. negative_prompt, num_images, seed and latents are also supported. Unrecognized
settings raise an error.
Seed compatibility. On CPU, the same seed gives the same image as diffusers with
generator=torch.Generator("cpu").manual_seed(seed) (validation). MPS and CUDA
runs are smoke tests only; there is no claim of exact equality on these devices.
Out of scope. There is no safety checker or invisible watermark. img2img, other schedulers and fp16 parity are not in this release.
License. The weights are licensed under MIT. imagehub does not distribute weights.
Stable Diffusion 2.1
Catalog: stable-diffusion-2 ·
Models: sd-v2-1 · Task: t2i
Architecture. A latent diffusion model with a frozen OpenCLIP-H text encoder, a U-Net with
linear-projection attention and an f=8 KL autoencoder. It is trained with v-prediction and sampled
with the checkpoint's DDIM scheduler (eta=0, set_alpha_to_one=false, steps_offset=1). The
U-Net config sets upcast_attention; the reference uses scaled dot-product attention, where the
flag has no effect, so the same output is produced. Its native image size is 768×768. The weights
come from sd2-community/stable-diffusion-2-1, a community copy of the withdrawn
stabilityai/stable-diffusion-2-1.
Usage.
from imagehub import pipeline

with pipeline("t2i", backend="sd-v2-1", model="checkpoints/sd-v2-1", device="mps") as pipe:
    result = pipe("a cat, oil painting", seed=42)
    result.images[0].save("cat.png")
Settings. steps defaults to 50, guidance defaults to 7.5 and width/height default to
768. negative_prompt, num_images, seed and latents are also supported. Unrecognized
settings raise an error.
Seed compatibility. On CPU, the same seed gives the same image as diffusers with
generator=torch.Generator("cpu").manual_seed(seed) (validation). MPS and CUDA
runs are smoke tests only; there is no claim of exact equality on these devices.
Out of scope. There is no safety checker or invisible watermark. img2img, other schedulers and fp16 parity are not in this release.
License. The weights use the CreativeML-OpenRAIL++-M license. imagehub does not distribute weights.
SD-Turbo
Catalog: sdxl-turbo (variant
"SD Turbo") · Models: sd-turbo · Task: t2i
Architecture. A distilled Stable Diffusion 2.1-based model with a frozen OpenCLIP-H text
encoder, U-Net and f=8 KL autoencoder. The checkpoint publishes an Euler scheduler with
timestep_spacing="trailing". Its native image size is 512×512.
Usage.
from imagehub import pipeline

with pipeline("t2i", backend="sd-turbo", model="checkpoints/sd-turbo", device="mps") as pipe:
    result = pipe("a cat, oil painting", seed=42)
    result.images[0].save("cat.png")
Settings. steps defaults to 1, guidance defaults to 0.0 and width/height default to
512. negative_prompt, num_images, seed and latents are also supported. Unrecognized
settings raise an error.
Seed compatibility. On CPU, the same seed gives the same image as diffusers with
generator=torch.Generator("cpu").manual_seed(seed) (validation). MPS and CUDA
runs are smoke tests only; there is no claim of exact equality on these devices.
Out of scope. There is no safety checker or invisible watermark. img2img, other schedulers and fp16 parity are not in this release.
License. The weights use the sai-nc-community license; see the license for its restrictions.
imagehub does not distribute weights.
Reference and imagehub, side by side
Drag the slider. Left is the recorded reference, right is imagehub, from the same seed, on CPU in float32.
 referenceimagehub
 referenceimagehub
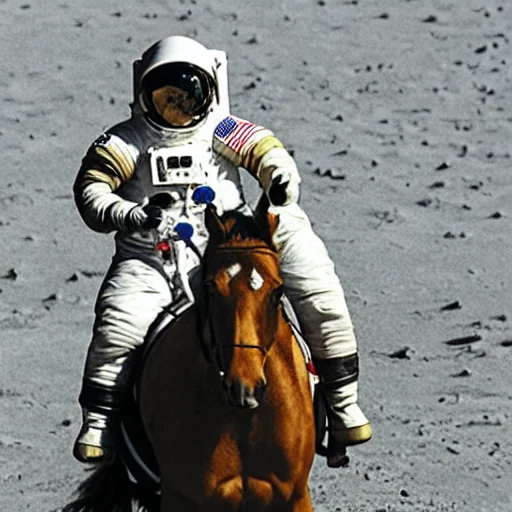
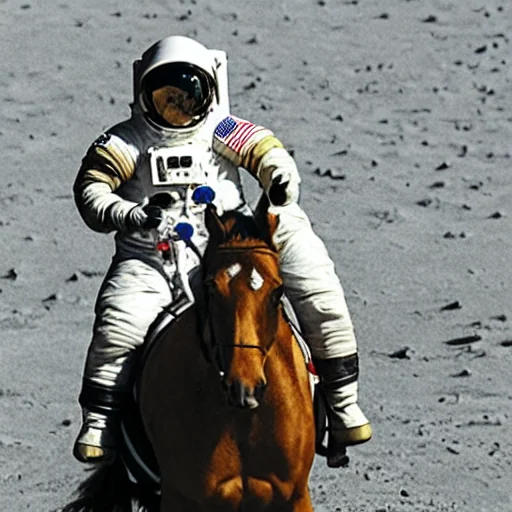 referenceimagehub
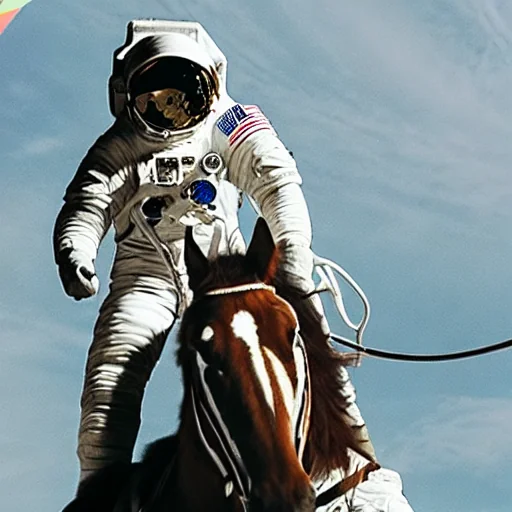
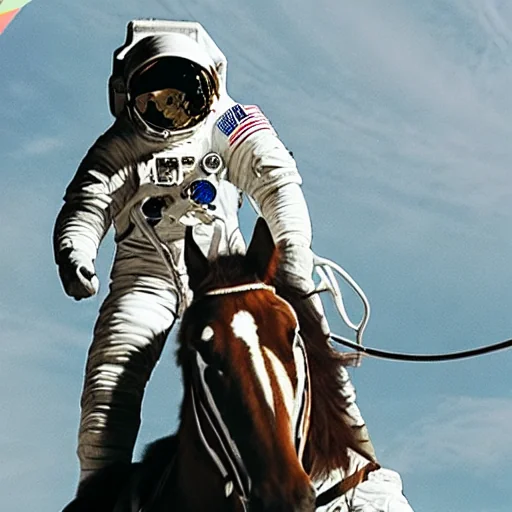 referenceimagehub
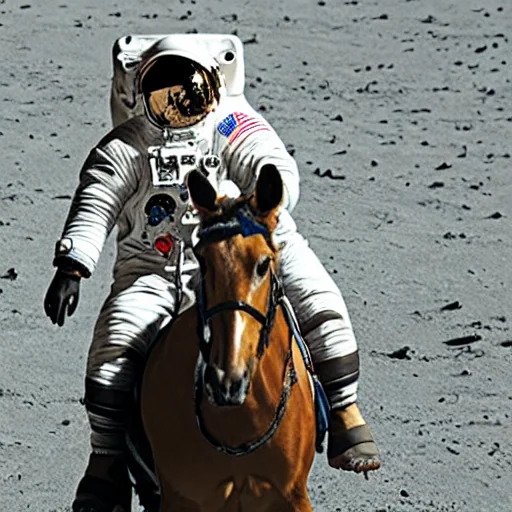
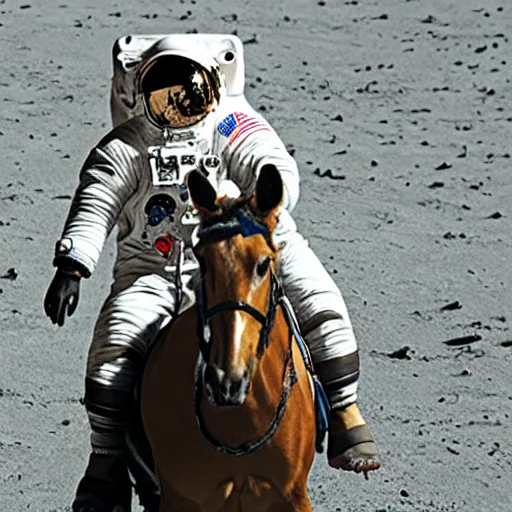 referenceimagehub
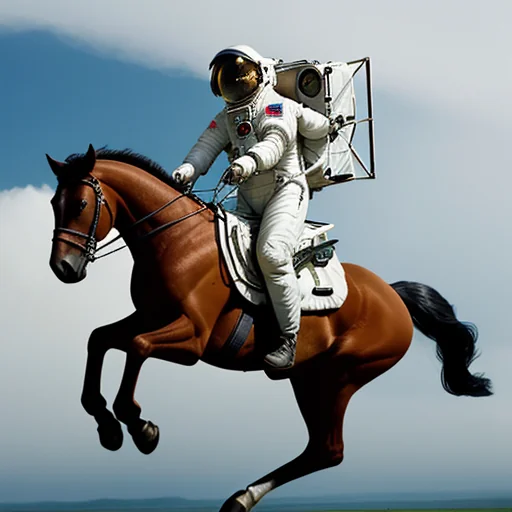
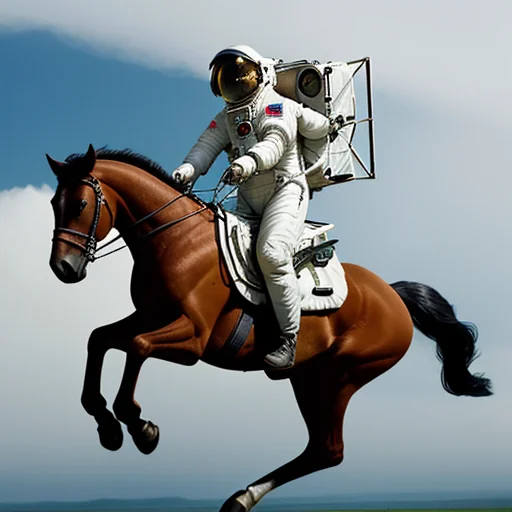 referenceimagehub
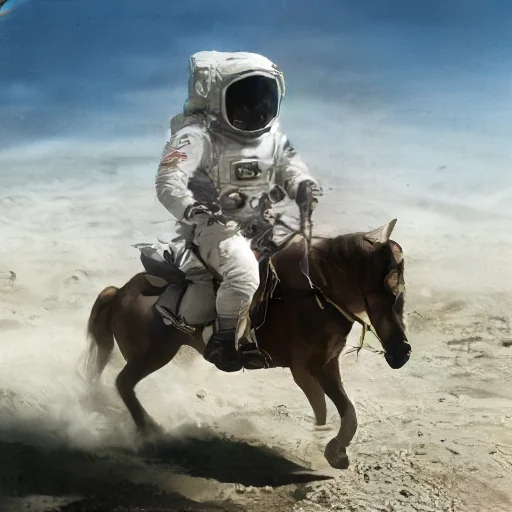
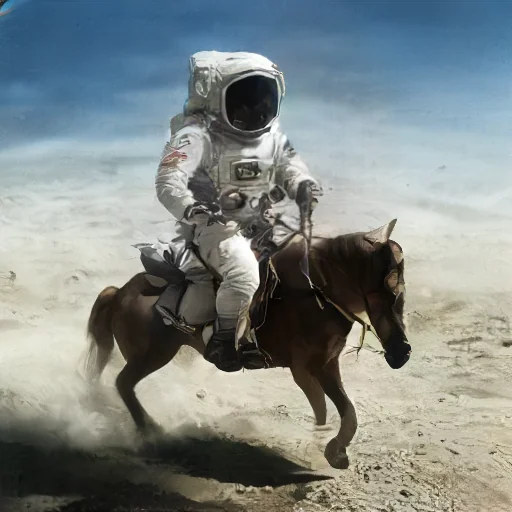 referenceimagehub
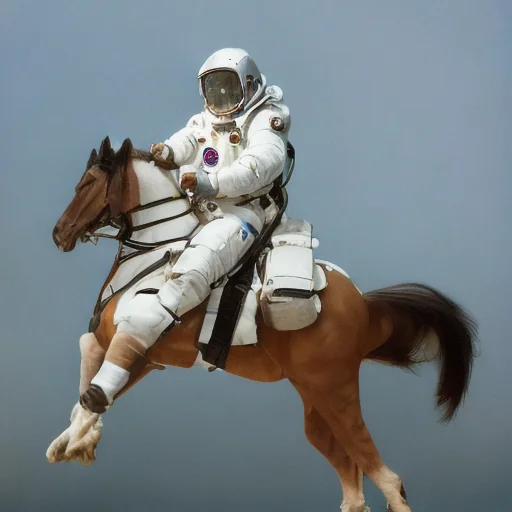
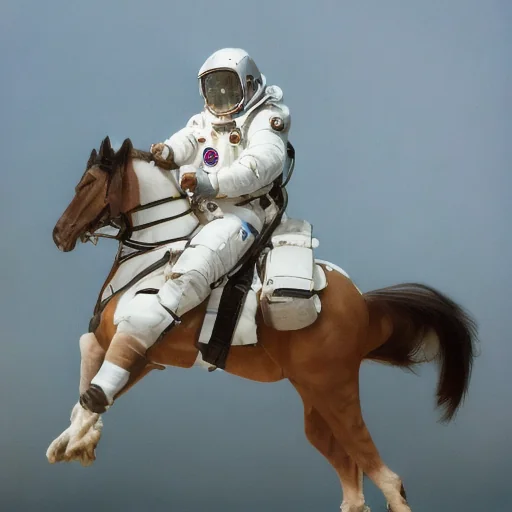 referenceimagehub
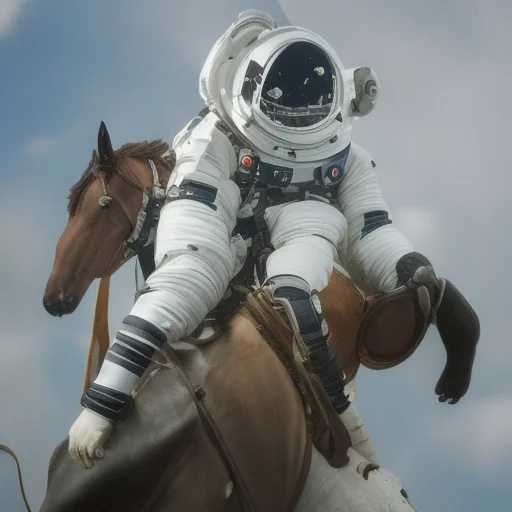
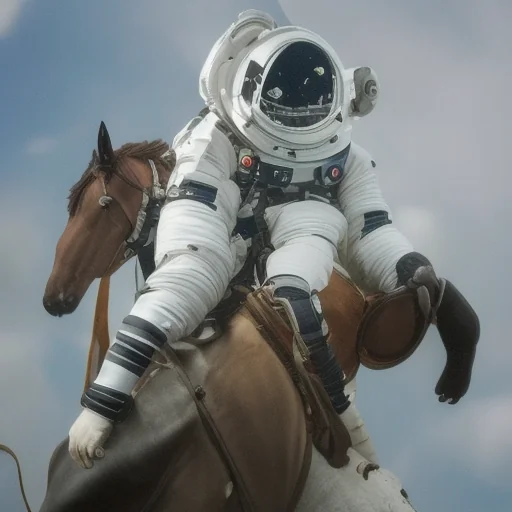 referenceimagehub
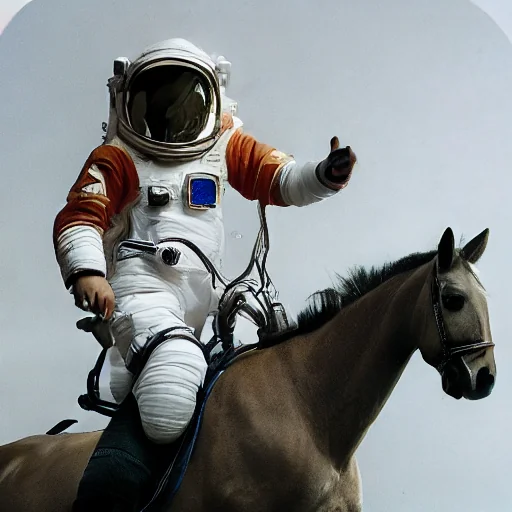
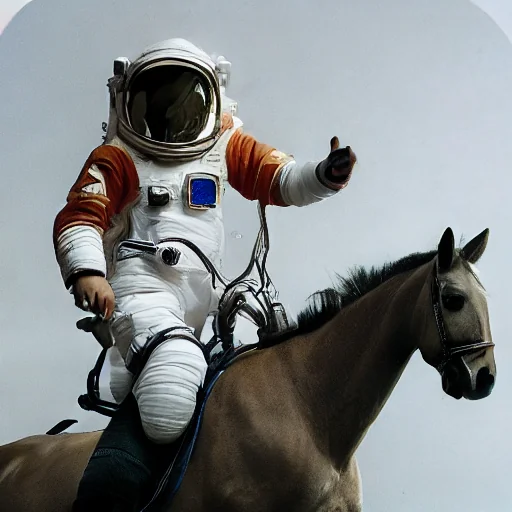 referenceimagehub
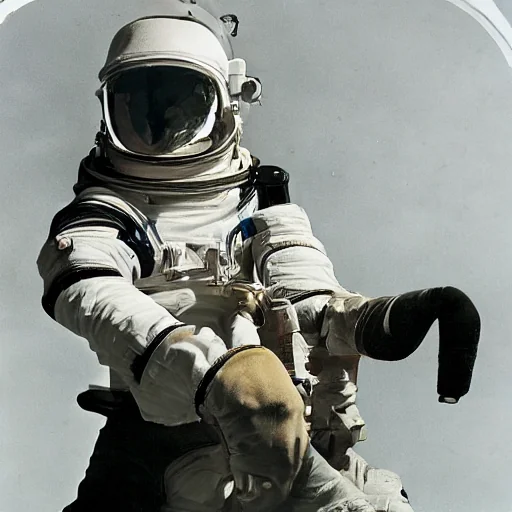
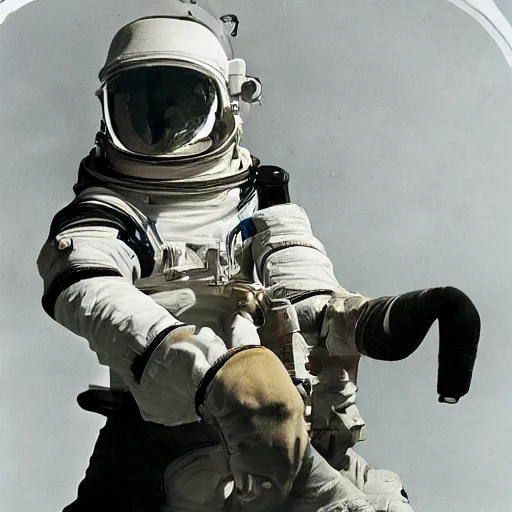 referenceimagehub
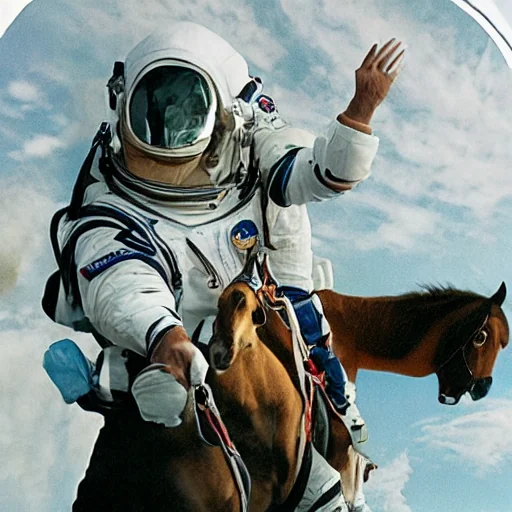
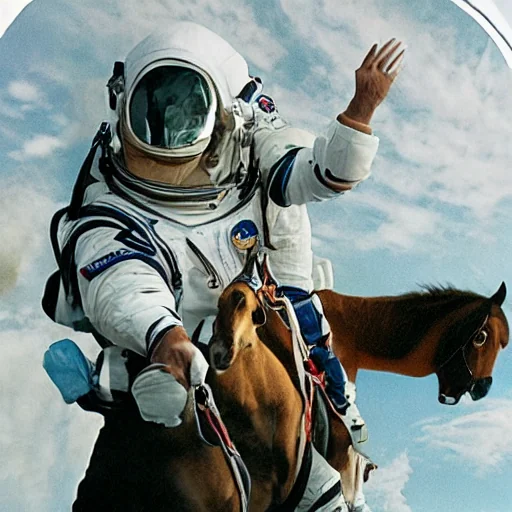 referenceimagehub
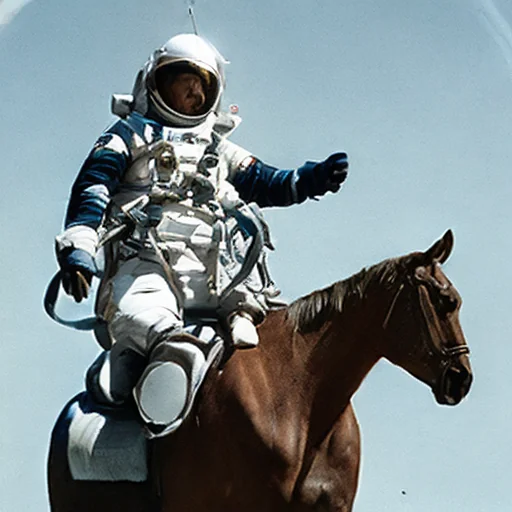
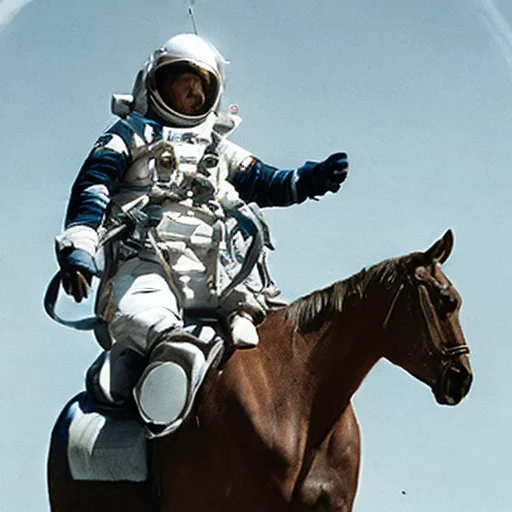 referenceimagehub
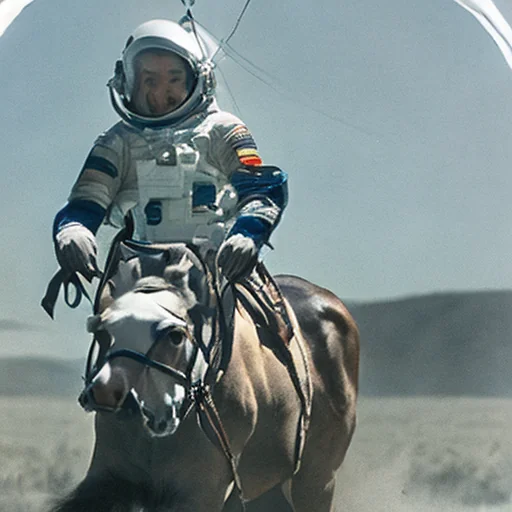
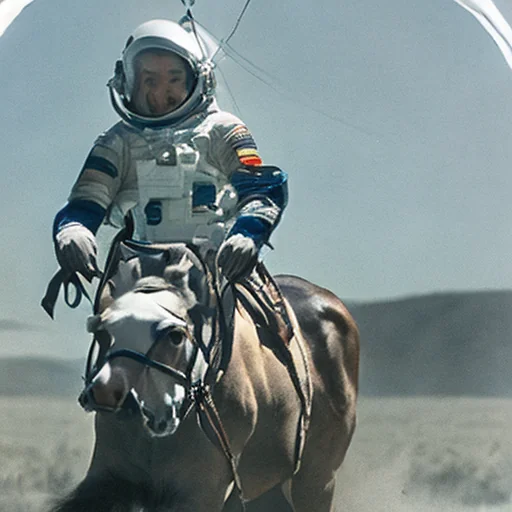 referenceimagehub
 referenceimagehub
 referenceimagehub
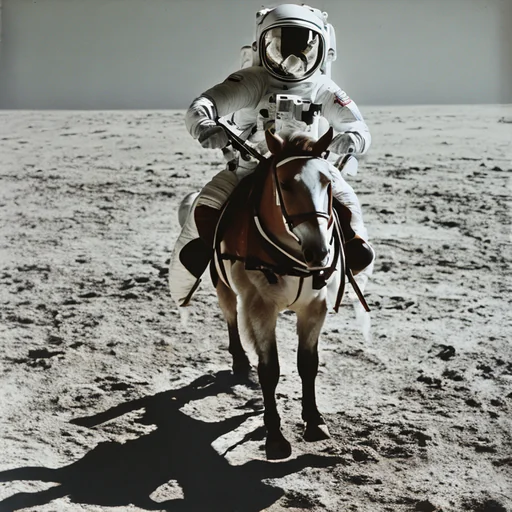
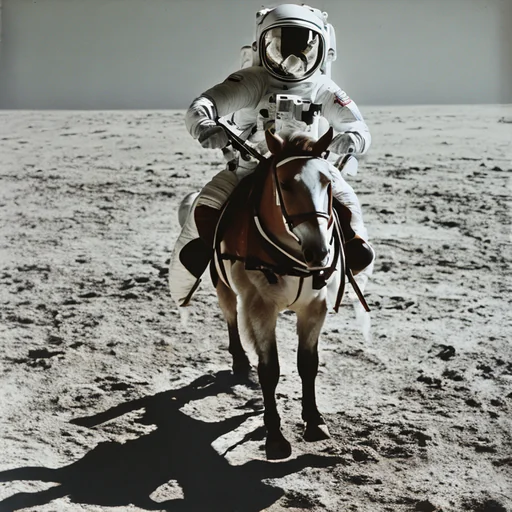 referenceimagehub
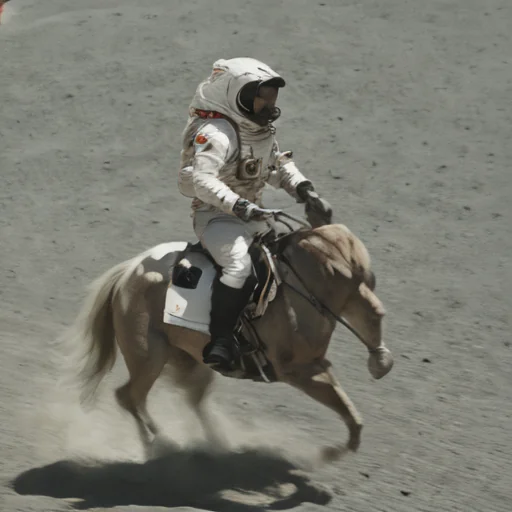
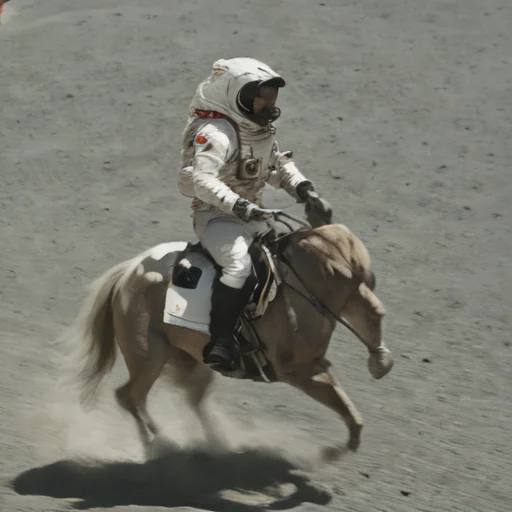 referenceimagehub