Sana
| Model | Source | Revision | Weight license | Parity (CPU, fp32) |
|---|---|---|---|---|
sana-1600m-1024 |
Efficient-Large-Model/Sana_1600M_1024px_diffusers | ac0da2f |
Apache-2.0 | Verified |
sana-600m-1024 |
Efficient-Large-Model/Sana_600M_1024px_diffusers | 28f3af7 |
Apache-2.0 | Verified |
sana-sprint-1.6b-1024 |
Efficient-Large-Model/Sana_Sprint_1.6B_1024px_diffusers | 19683c5 |
Apache-2.0 | Verified |
sana-1.5-4.8b-1024 |
Efficient-Large-Model/SANA1.5_4.8B_1024px_diffusers | 9468102 |
Apache-2.0 | Verified |
Catalog: sana · Models:
sana-1600m-1024, sana-600m-1024, sana-sprint-1.6b-1024, sana-1.5-4.8b-1024 · Task: t2i
Architecture. A Gemma-2 2B text model (26 layers, width 2304, soft-capped attention and
alternating sliding-window layers) encodes the prompt, and its last hidden state conditions a linear
diffusion transformer. The transformer applies ReLU linear attention over the image tokens,
cross-attention to the masked text, GLUMBConv feed-forward blocks and AdaLN-single timestep
modulation. The 1600M model has 20 blocks of width 2240 and the 600M model has 28 blocks of width
1152. The 1.5 4.8B model uses 60 blocks of width 2240 with qk normalization. The Sprint 1.6B model
keeps the 1600M width but replaces the timestep embedding with a combined timestep + guidance
embedding and uses the single-step consistent-model (SCM) scheduler with trigflow parameterization.
Images are decoded by the DC-AE autoencoder, which compresses 32× into 32 latent channels
(scaling factor 0.41407). The standard models use the order-2 midpoint DPM-Solver++ with flow
sigmas and flow_shift 3.0; Sprint uses the 2-step SCM schedule. Before encoding, a "complex human
instruction" is prepended to the prompt, and the first token plus the last 299 tokens of the encoder
output are kept.
Usage.
from imagehub import pipeline

with pipeline(
    "t2i", backend="sana-1600m-1024", model="checkpoints/sana-1600m-1024", device="mps"
) as pipe:
    result = pipe("a cat, oil painting", seed=42)
    result.images[0].save("cat.png")
Settings. All models default to guidance 4.5 and 1024×1024, with an empty negative prompt.
sana-1600m-1024, sana-600m-1024 and sana-1.5-4.8b-1024 default to 20 steps; the standard
options are seed, steps, guidance, width, height, negative_prompt,
use_resolution_binning, max_sequence_length (default 300) and complex_human_instruction.
sana-sprint-1.6b-1024 defaults to 2 steps, ignores negative_prompt (guidance is embedded via the
transformer) and supports the same remaining options. With use_resolution_binning on (the default),
the requested size is snapped to the closest aspect-ratio bin, the image is generated at the bin
size, and the decoded image is resized and centre-cropped back to the request; turn it off to
generate at the exact size, which must then be a multiple of 32. complex_human_instruction is a
list of strings; None selects the published instruction and an empty list disables it. The
instruction is never added to the negative prompt. Guidance 1.0 or lower skips the unconditional pass
for standard models. Unrecognized settings raise an error.
Memory. In float32 the 1600M transformer needs about 6.4 GB (2.4 GB for the 600M model), the Gemma-2 text model about 10.5 GB and DC-AE about 1.3 GB. The 1.5 4.8B and Sprint transformers need roughly 9–10 GB. The Gemma-2 weights are stored in bfloat16 and upcast on load.
Seed compatibility. On CPU, the same seed and settings give the same image as diffusers with
generator=torch.Generator("cpu").manual_seed(seed) (validation). MPS and CUDA
runs are smoke tests only; there is no claim of exact equality on these devices.
Out of scope. The 2K and 4K checkpoints, ControlNet, PAG, fp16/bf16 parity and caption cleaning
are not supported. Caption cleaning requires external packages; parity is against
clean_caption=False. Only decoding is exposed for DC-AE.
License. All repositories declare the Apache-2.0 license. The text encoder is a Gemma-2 checkpoint; check Google's Gemma terms of use before redistributing it. imagehub does not distribute weights.
Reference and imagehub, side by side
Drag the slider. Left is the recorded reference, right is imagehub, from the same seed, on CPU in float32.
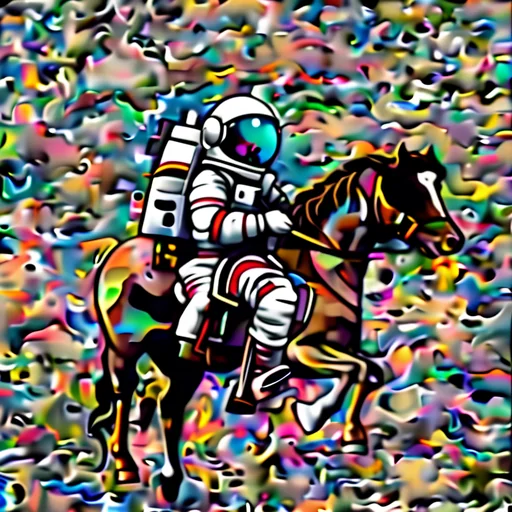
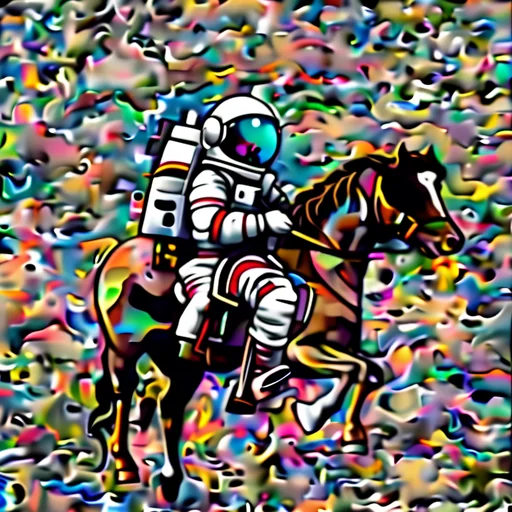 referenceimagehub
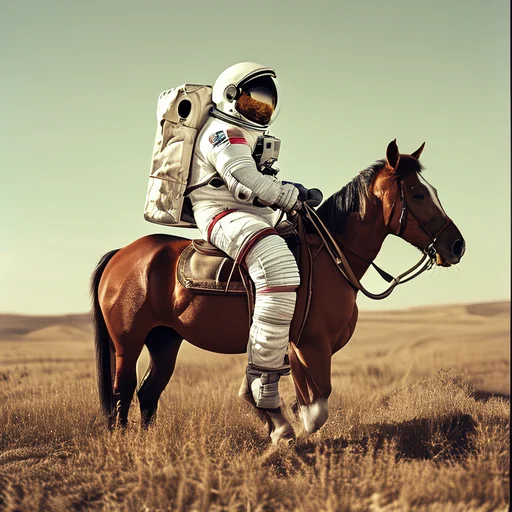
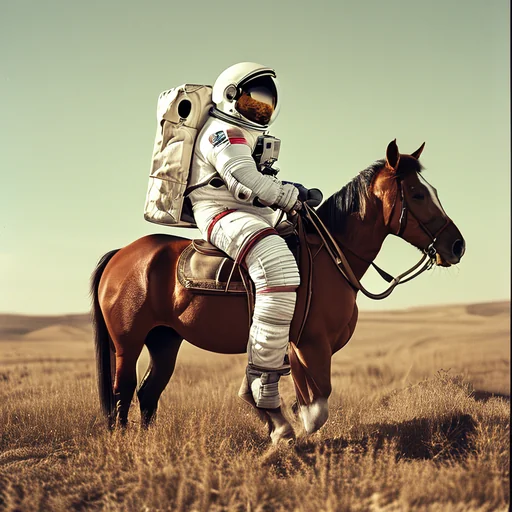 referenceimagehub
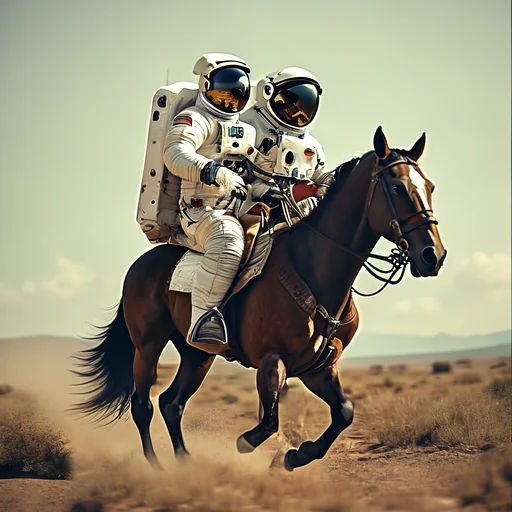
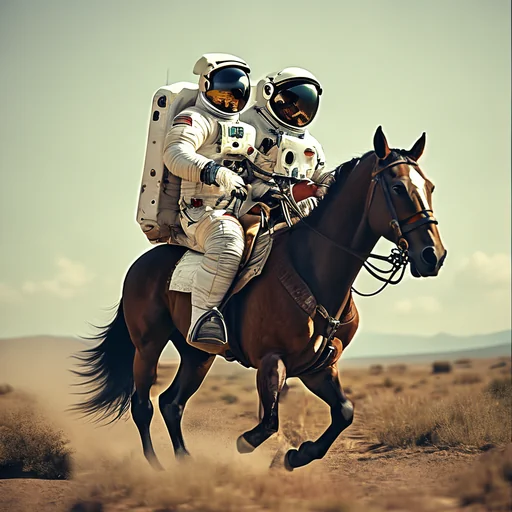 referenceimagehub
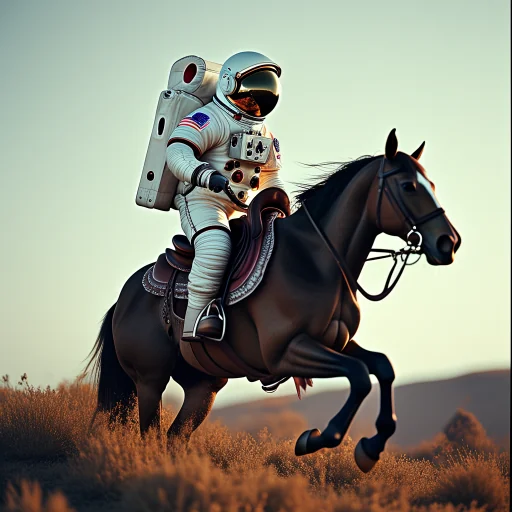
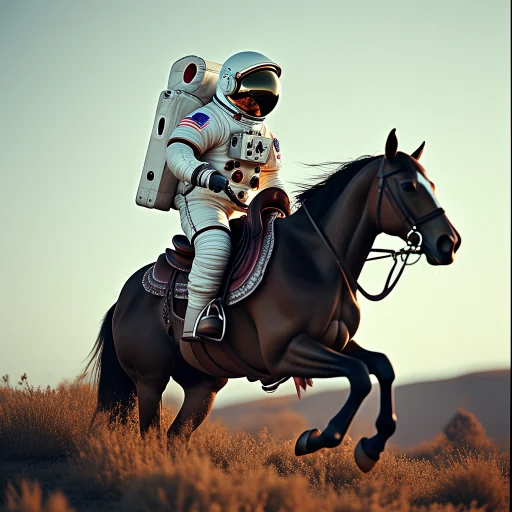 referenceimagehub