CogView3-Plus
| Model | Source | Revision | Weight license | Parity (CPU, fp32) |
|---|---|---|---|---|
cogview3-plus-3b |
zai-org/CogView3-Plus-3B | 5d70e40 |
Apache-2.0 | Verified |
Catalog: cogview3-plus ·
Models: cogview3-plus-3b · Task: t2i
Architecture. A T5-XXL encoder (24 layers, width 4096) supplies the prompt features, padded to
224 tokens and used without an attention mask. A 3B diffusion transformer with 30 blocks and 64
attention heads of width 40 attends jointly over text and image tokens; each block is modulated by
AdaLN-Zero from a timestep embedding plus SDXL-style original-size, target-size and crop-coordinate
conditions. Image tokens receive a fixed 2D sine-cosine position embedding. A 16-channel VAE with
scaling factor 1.0 decodes the latents. The scheduler is a DDIM sampler with shifted SNR
(CogVideoXDDIMScheduler, trailing spacing, zero terminal SNR, v-prediction). The native image
size is 1024×1024.
Usage.
from imagehub import pipeline

with pipeline(
    "t2i", backend="cogview3-plus-3b", model="checkpoints/cogview3-plus-3b", device="mps"
) as pipe:
    result = pipe("a cat, oil painting", seed=42)
    result.images[0].save("cat.png")
Settings. steps defaults to 50, guidance defaults to 5.0, width/height default to 1024
and max_sequence_length defaults to 224. The other supported options are seed, latents,
negative_prompt, original_size and crops_coords_top_left. width and height must be
multiples of 16 and at most 2048. Guidance is applied when it is greater than 1. Without a
negative_prompt the unconditional features are zeros, as in the reference pipeline; an explicit
negative_prompt (even an empty string) is encoded by the text encoder. Unrecognized settings raise
an error.
Seed compatibility. On CPU, the same seed and settings give the same image as diffusers with
generator=torch.Generator("cpu").manual_seed(seed) (validation). MPS and CUDA
runs are smoke tests only; there is no claim of exact equality on these devices.
Out of scope. The CogVideoXDPMScheduler, stochastic sampling (eta above 0), multiple images
per prompt, prompt embeddings passed in directly and fp16/bf16 parity are not supported. The
published transformer and VAE weights are bfloat16; CPU parity is measured in float32 after
upcasting. In float32 the text encoder needs about 19 GB and the transformer about 11 GB.
License. The weights use the Apache-2.0 license. imagehub does not distribute weights.
Reference and imagehub, side by side
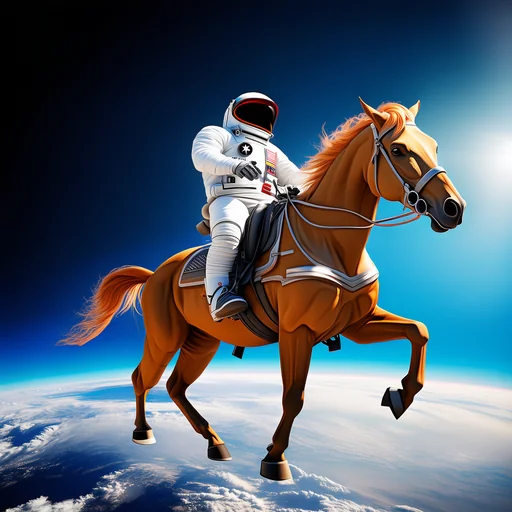
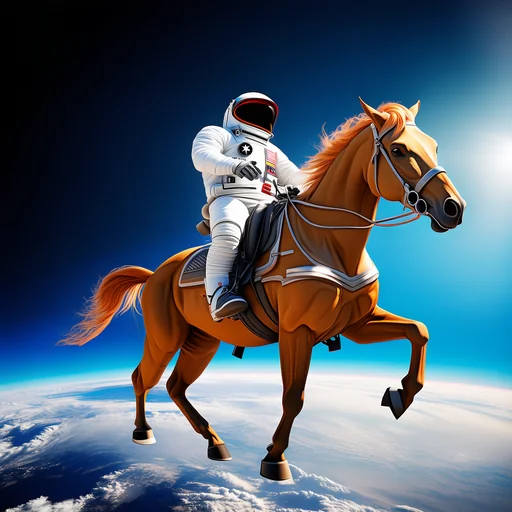
Drag the slider. Left is the recorded reference, right is imagehub, from the same seed, on CPU in float32.
 referenceimagehub