Kolors
| Model | Source | Revision | Weight license | Parity (CPU, fp32) |
|---|---|---|---|---|
kolors |
Kwai-Kolors/Kolors-diffusers | 7e091c7 |
Apache-2.0 | Verified |
Catalog: kolors · Models:
kolors · Task: t2i
Architecture. A ChatGLM3-6B text encoder (28 layers, width 4096, grouped-query attention with
two key/value groups, rotary embeddings, RMSNorm) encodes the prompt, left-padded to 256 tokens
with a [gMASK] sop prefix. The input of the last encoder block, as [256, 4096], is the
cross-attention context and the last position of the last block's output, as [4096], is the
pooled vector. The generator is an SDXL-style U-Net (three levels, 320/640/1280 channels,
transformer depths 1/2/10) whose cross-attention width of 2048 is reached by a linear projection of
the 4096-wide context. The pooled vector and the six size and crop values are embedded as in SDXL
and added to the timestep embedding. Images are decoded by the SDXL-style KL autoencoder (scaling
factor 0.13025). The scheduler is Euler discrete with 1100 training steps, leading spacing and a
beta range ending at 0.014.
Usage.
from imagehub import pipeline

with pipeline("t2i", backend="kolors", model="checkpoints/kolors", device="mps") as pipe:
    result = pipe("a cat, oil painting", seed=42)
    result.images[0].save("cat.png")
Settings. The defaults are 50 steps, guidance 5.0 and 1024×1024. The negative prompt defaults
to the empty string, which is encoded like any other (Kolors does not zero it). The supported
options are seed, latents, steps, guidance, width, height, num_images,
negative_prompt, original_size, crops_coords_top_left and target_size; the last three are
the SDXL micro-conditioning values and default to the image size and (0, 0). Width and height
must be multiples of 8 and steps at most 1100. Guidance 1.0 or lower skips the unconditional
pass. Prompts are truncated to 256 tokens. Unrecognized settings raise an error.
Weights. Only float16 weights are published, so the snapshot holds *.fp16.safetensors files
and a float16 shard index for the text encoder. They are read directly and upcast to float32 on
load; parity is measured on that upcast, against diffusers loaded with variant="fp16" and
torch_dtype=torch.float32. A float16 VAE with force_upcast decodes in float32 and is restored
afterwards.
Memory. In float32 the U-Net needs about 10.3 GB, the ChatGLM3 text encoder about 25 GB and the autoencoder about 0.3 GB; the float16 files total about half of that.
Seed compatibility. On CPU, the same seed and settings give the same image as diffusers with
generator=torch.Generator("cpu").manual_seed(seed) (validation). MPS and CUDA
runs are smoke tests only; there is no claim of exact equality on these devices.
Out of scope. Kolors IP-Adapter, ControlNet and inpainting variants, LoRA, prompts longer
than 256 tokens, other schedulers, denoising_end, negative micro-conditioning and
precomputed prompt embeddings are not supported.
License. The repository declares the Apache-2.0 license. imagehub does not distribute weights.
Reference and imagehub, side by side
Drag the slider. Left is the recorded reference, right is imagehub, from the same seed, on CPU in float32.
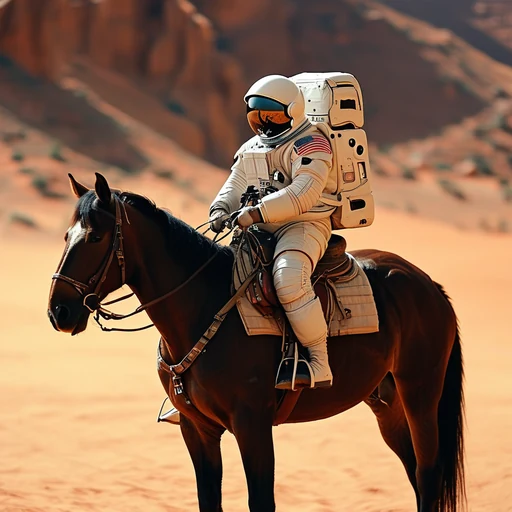
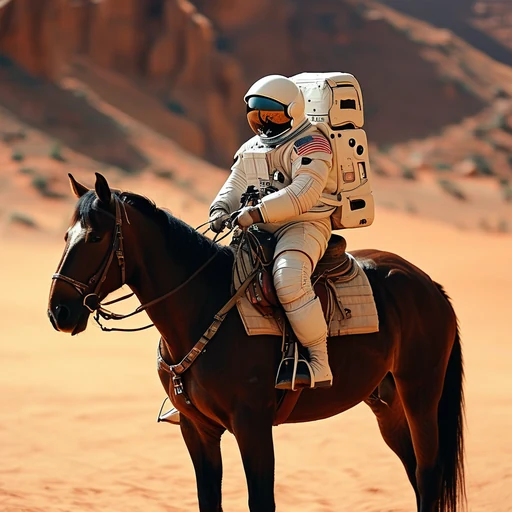 referenceimagehub