OmniGen
| Model | Source | Revision | Weight license | Parity (CPU, fp32) |
|---|---|---|---|---|
omnigen-v1 (+ image input) |
Shitao/OmniGen-v1-diffusers | 016e2f6 |
MIT | Verified |
Catalog: omnigen ·
Models: omnigen-v1 · Task: t2i
Architecture. One 3.8B-parameter transformer initialized from Phi-3 mini (32 layers, width 3072,
32 heads, a fused gate-and-up MLP, RMSNorm, "su"-scaled rotary embeddings) reads text tokens,
VAE-encoded input-image patches and the noisy-image patches as one sequence. Text and input-image
tokens attend causally; the image tokens of one image attend to each other, and the noisy-image tokens
attend to everything. The latents come from the 4-channel SDXL-style autoencoder (scaling factor
0.13025) in 2×2 patches, with separate patch projections for input and output images and a stored
sin-cos position table. The scheduler is flow-match Euler with the sigmas inverted, so the model sees
a time that grows from 0 to 1. The prompt is wrapped in a chat-style instruction (<|user|>, "Generate
an image according to the following instructions", <|assistant|>, <|diffusion|>) and tokenized
with the Phi-3 Llama-style BPE tokenizer.
Usage.
from PIL import Image
from imagehub import pipeline

with pipeline("t2i", backend="omnigen-v1", model="checkpoints/omnigen-v1", device="mps") as pipe:
    result = pipe("a cat, oil painting", seed=42)
    result.images[0].save("cat.png")

    # Editing: the prompt refers to the input image with the placeholder.
    edited = pipe(
        "Turn <img><|image_1|></img> into a watercolor painting.",
        image=Image.open("photo.png"),
        seed=42,
    )
    edited.images[0].save("edited.png")
Image input (optional). One input image is accepted through image (a PIL.Image.Image or an
imagehub.Image; other PIL modes are converted to RGB). The prompt must reference it with the exact
placeholder <img><|image_1|></img>, which can appear anywhere in the text and more than once. Without
an image the prompt must not contain a placeholder. Several input images (<|image_2|>, ...) are not
supported. The image is shrunk (box filter while both sides are at least twice
max_input_image_size, then bicubic to at most max_input_image_size on the long side, default 1024),
cropped evenly to multiples of 16 and encoded by the autoencoder; each placeholder becomes one image
token per 16×16 pixels. With an image, three predictions are made per step (prompt, negative prompt,
image-only prompt) and combined as uncond + image_guidance * (img_cond - uncond) + guidance * (cond -
img_cond). use_input_image_size_as_output=True generates at the preprocessed input size, which is
the setting for editing.
Settings. The model defaults to 50 steps, guidance 2.5, image guidance 1.6 and 1024×1024. The
supported options are seed, steps, guidance, image_guidance (used only with an image), width,
height (multiples of 16, at most 3072), image, max_input_image_size and
use_input_image_size_as_output. The negative prompt is fixed by the model (a list of quality terms).
Guidance is always applied, including at 1.0. Unrecognized settings raise an error.
Seed compatibility. The initial noise is torch.randn from torch.Generator("cpu").manual_seed(seed),
as with the other models. The reference pipeline samples the input-image posterior from the global
torch generator, so a reference run that uses an image must call torch.manual_seed(seed) before the
pipeline; imagehub draws that noise from a second generator seeded with the same value, which gives
the same stream. On CPU the same seed and settings then give the same image as diffusers 0.40.0
(validation). MPS and CUDA runs are smoke tests only; there is no claim of exact
equality on these devices.
Memory. The repository stores the transformer in bfloat16 (7.8 GB); in float32 it needs about 15.5 GB, and the autoencoder about 0.3 GB. At 1024×1024 the sequence has more than 4,200 tokens per branch, so a CPU step takes minutes.
Out of scope. Several input images, num_images_per_prompt above 1, batches of prompts, a custom
negative prompt, caller-supplied latents, callbacks, LoRA and fp16/bf16 parity are not supported.
License. The repository declares the MIT license. imagehub does not distribute weights.
Reference and imagehub, side by side
Drag the slider. Left is the recorded reference, right is imagehub, from the same seed, on CPU in float32.
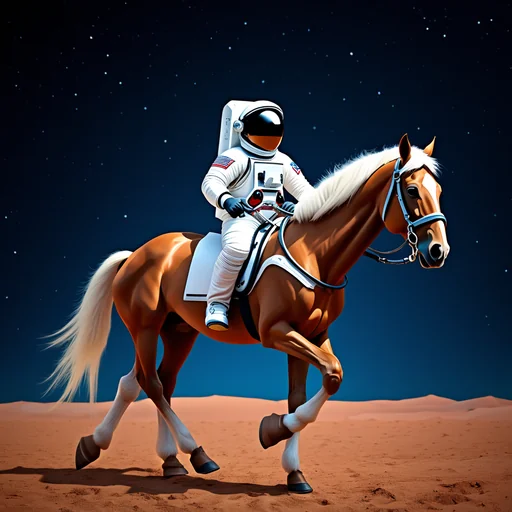
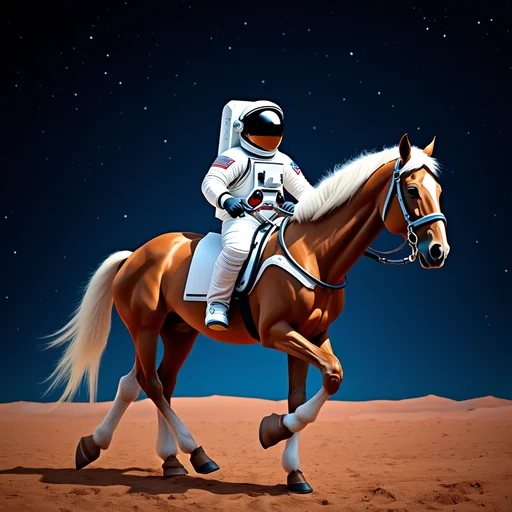 referenceimagehub