PixArt
| Model | Source | Revision | Weight license | Parity (CPU, fp32) |
|---|---|---|---|---|
pixart-sigma-xl-1024 |
PixArt-alpha/PixArt-Sigma-XL-2-1024-MS | e102b35 |
CreativeML-OpenRAIL++-M | Verified |
pixart-sigma-xl-512 |
PixArt-alpha/PixArt-Sigma-XL-2-512-MS | 76fb7eb |
CreativeML-OpenRAIL++-M | Verified |
pixart-sigma-xl-256 |
PixArt-alpha/PixArt-Sigma-XL-2-256x256 | 495cb1b |
OpenRAIL (exact terms unspecified) | Verified |
pixart-sigma-xl-2k |
PixArt-alpha/PixArt-Sigma-XL-2-2K-MS | cd274f4 |
OpenRAIL (exact terms unspecified) | Verified |
pixart-alpha-xl-1024 |
PixArt-alpha/PixArt-XL-2-1024-MS | b89adad |
CreativeML-OpenRAIL++-M | Verified |
pixart-alpha-xl-512 |
PixArt-alpha/PixArt-XL-2-512x512 | 50f7021 |
CreativeML-OpenRAIL++-M | Verified |
pixart-lcm-xl-1024 |
PixArt-alpha/PixArt-LCM-XL-2-1024-MS | e153060 |
CreativeML-OpenRAIL++-M | Verified |
Catalog: pixart-sigma,
pixart-alpha · Models:
pixart-sigma-xl-1024, pixart-sigma-xl-512, pixart-sigma-xl-256, pixart-sigma-xl-2k,
pixart-alpha-xl-1024, pixart-alpha-xl-512, pixart-lcm-xl-1024 · Task: t2i
Architecture. A T5-v1.1-XXL text encoder supplies up to 300 tokens for Sigma and 120 for Alpha
to a 0.6B diffusion transformer with 28 blocks, width 1152 and 16 attention heads of width 72. The
transformer uses shared ada_norm_single timestep modulation, caption projection, a 2D sine-cosine
position embedding and learned sigma prediction. Sigma uses interpolation scale 2 and the SDXL VAE
with scaling factor 0.13025. Alpha adds resolution and aspect-ratio embeddings and uses the SD VAE
with scaling factor 0.18215. Both use the order-2 midpoint DPM-Solver++ multistep scheduler and bin
requested resolutions to their supported aspect-ratio tables. PixArt-LCM reuses the Alpha layout with
an LCM scheduler and its own distilled transformer.
Usage.
from imagehub import pipeline

with pipeline(
    "t2i", backend="pixart-sigma-xl-1024", model="checkpoints/pixart-sigma-xl-1024", device="mps"
) as pipe:
    result = pipe("a cat, oil painting", seed=42, negative_prompt="blurry")
    result.images[0].save("cat.png")
Resolutions. Each resolution is a separate checkpoint with its own transformer: Sigma at 256,
512, 1024 and 2K (interpolation scales 0.5, 1, 2 and 4) and Alpha at 512 and 1024. The Sigma 256, 512 and
2K repositories publish only a transformer, so python -m imagehub.pretrained fetches the text
encoder, tokenizer, VAE and scheduler from the Sigma 1024 repository, as the model cards describe. The
Alpha resolution and aspect-ratio embeddings exist only in the 1024 model. Resolution binning
uses the table that matches the transformer (256, 512, 1024 or 2048).
Settings. PixArt-LCM defaults to 4 steps, guidance 0.0 and 1024×1024 output; all other models
default to 20 steps and guidance 4.5, and to a square image of their native size (256, 512, 1024 or
2048 pixels). Sigma defaults to a maximum sequence length of 300 and Alpha and LCM to 120. The other supported options are seed, latents,
negative_prompt, use_resolution_binning and max_sequence_length. Unrecognized settings raise
an error.
Seed compatibility. On CPU, the same seed and settings give the same image as diffusers with
generator=torch.Generator("cpu").manual_seed(seed) (validation). MPS and CUDA
runs are smoke tests only; there is no claim of exact equality on these devices.
Out of scope. PixArt-DMD, ControlNet,
fp16/bf16 parity and caption cleaning are not supported. Caption cleaning requires bs4 and ftfy;
parity is against clean_caption=False, which diffusers uses when those packages are unavailable.
License. Both models use the CreativeML-OpenRAIL++-M license. imagehub does not distribute weights.
Reference and imagehub, side by side
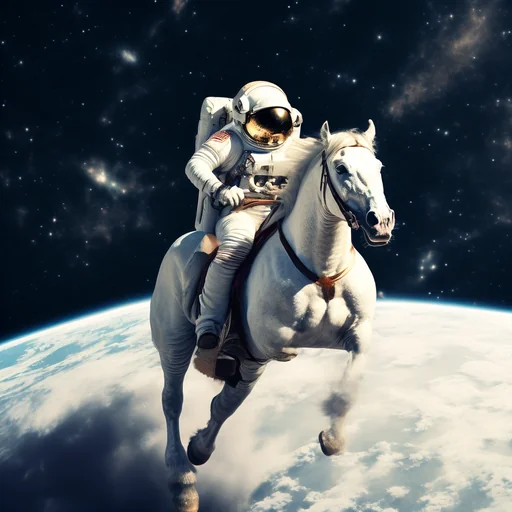
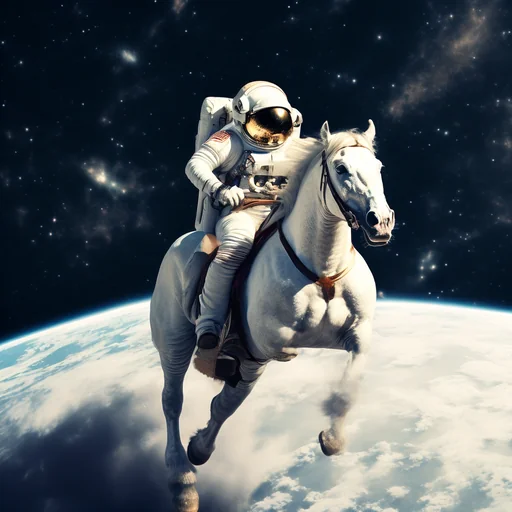
Drag the slider. Left is the recorded reference, right is imagehub, from the same seed, on CPU in float32.
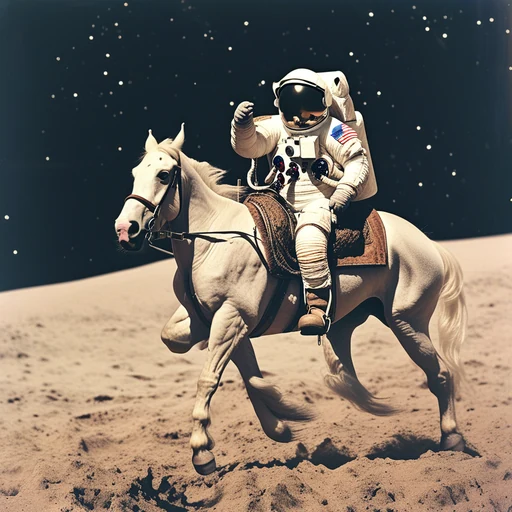
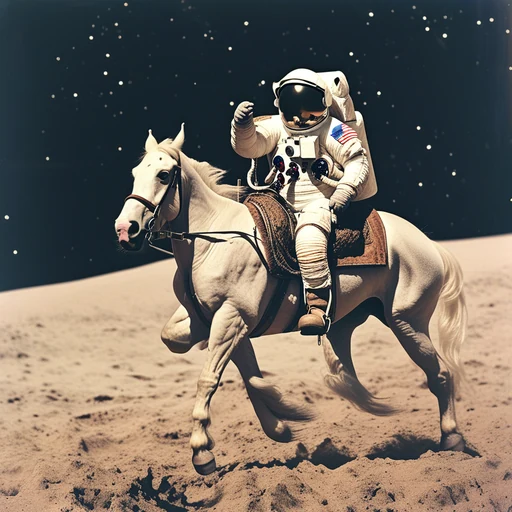 referenceimagehub
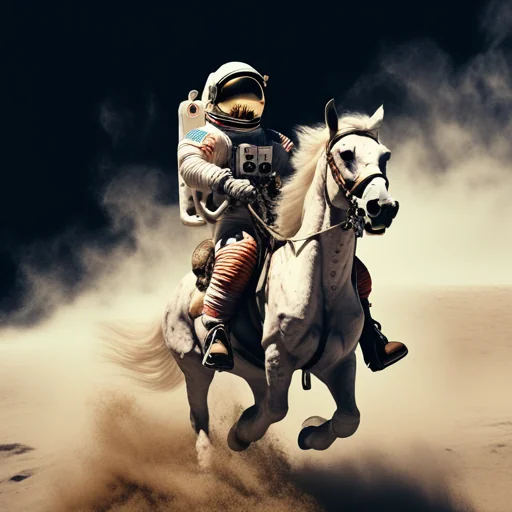
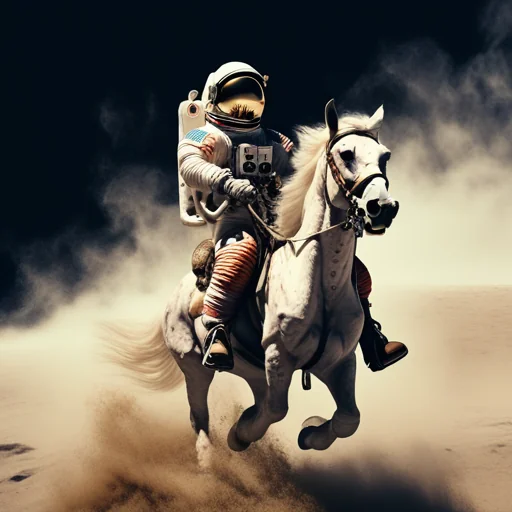 referenceimagehub
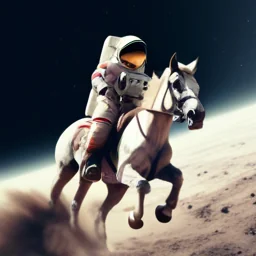
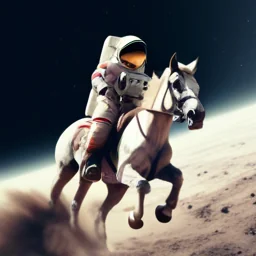 referenceimagehub
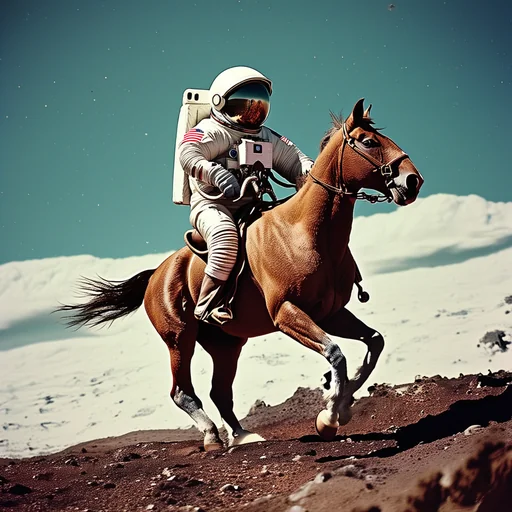
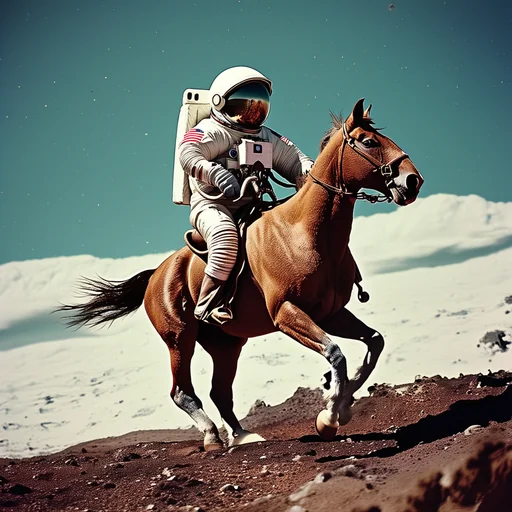 referenceimagehub
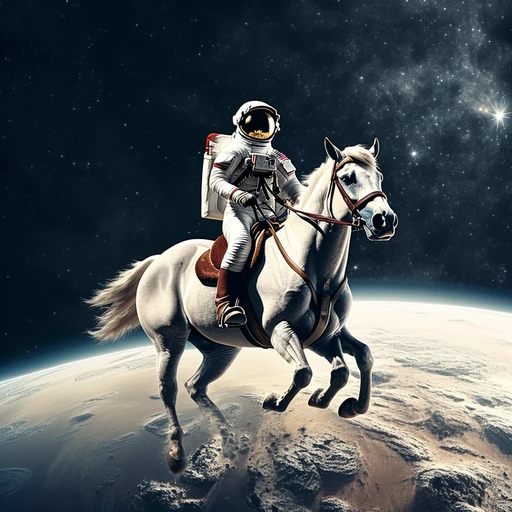
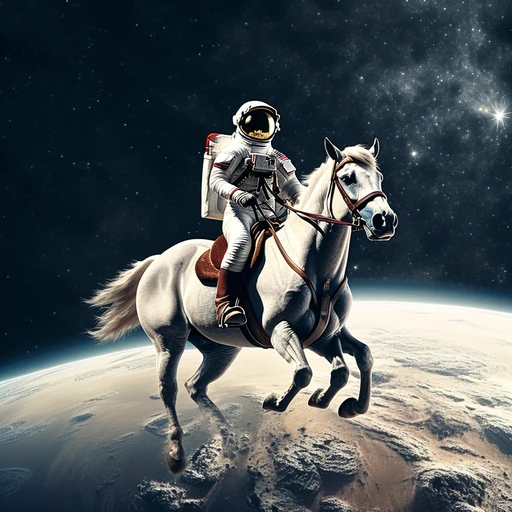 referenceimagehub
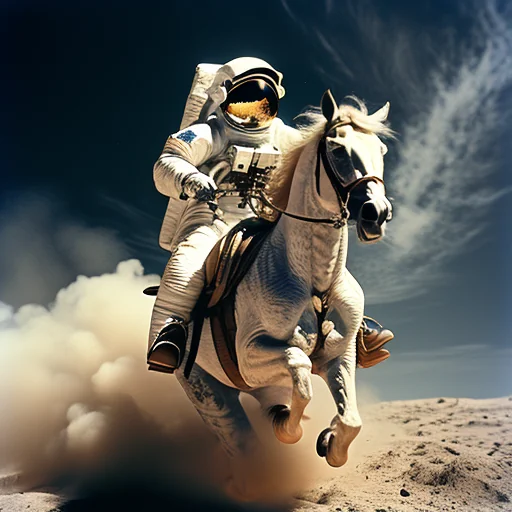
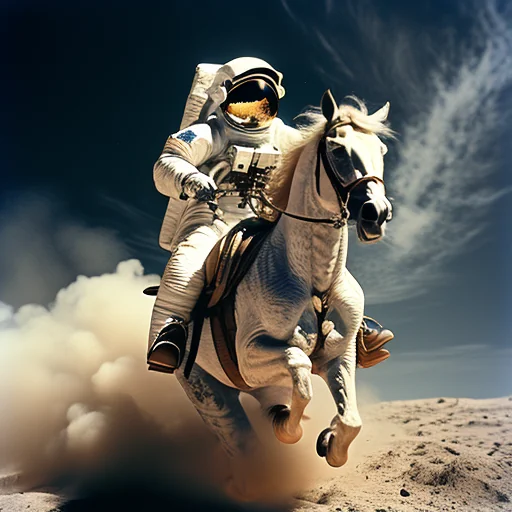 referenceimagehub
 referenceimagehub