Lumina-Image 2.0
| Model | Source | Revision | Weight license | Parity (CPU, fp32) |
|---|---|---|---|---|
lumina-image-2.0 |
Alpha-VLLM/Lumina-Image-2.0 | 53504ab |
Apache-2.0 | Verified |
Catalog: lumina-image-2 ·
Models: lumina-image-2.0 · Task: t2i
Architecture. A Gemma-2 2B text model (26 layers, width 2304) encodes the prompt, and its
second-to-last hidden state conditions a 2.6B-parameter Next-DiT transformer. The transformer has 26
joint blocks of width 2304 (24 attention heads, 8 key-value heads) and two refiner blocks each for the
text and for the image tokens. It uses 3D rotary position embeddings over the text position and the
image row and column, sandwich normalization, and timestep modulation in the image refiner and joint blocks. The transformer works on
2×2 patches of the 16-channel latents from the FLUX-style autoencoder (scaling factor 0.3611, shift
factor 0.1159). The scheduler is flow-match Euler with a static shift of 6.0. The model treats t=0 as
noise, so the timestep is reversed and the prediction is negated before each step. Before encoding, a
system prompt and the marker <Prompt Start> are prepended to the prompt; the negative prompt is
encoded without them.
Usage.
from imagehub import pipeline

with pipeline(
    "t2i", backend="lumina-image-2.0", model="checkpoints/lumina-image-2.0", device="mps"
) as pipe:
    result = pipe("a cat, oil painting", seed=42)
    result.images[0].save("cat.png")
Settings. The model defaults to 30 steps, guidance 4.0 and 1024×1024, with an empty negative
prompt. The supported options are seed, steps, guidance, width, height,
negative_prompt, system_prompt, cfg_trunc_ratio (default 1.0), cfg_normalization (default
true) and max_sequence_length (default 256, at most 299 for the published model). width and
height must be multiples of 16. system_prompt replaces the published system prompt; None
selects it. Guidance is applied as uncond + guidance * (cond - uncond); with cfg_normalization
the result is rescaled to the norm of the conditional prediction. The unconditional pass is skipped
for steps after the fraction cfg_trunc_ratio of the schedule, so 1.0 guides every step. Guidance
1.0 or lower skips the unconditional pass entirely. Unrecognized settings raise an error.
Memory. In float32 the transformer needs about 10.4 GB, the Gemma-2 text model about 10.5 GB and the autoencoder about 0.3 GB.
Seed compatibility. On CPU, the same seed and settings give the same image as diffusers with
generator=torch.Generator("cpu").manual_seed(seed) (validation). MPS and CUDA
runs are smoke tests only; there is no claim of exact equality on these devices.
Out of scope. fp16/bf16 parity, batches of several prompts or images per call, and caller-supplied latents or embeddings are not supported.
License. The repository declares the Apache-2.0 license. The text encoder is a Gemma-2 checkpoint; check Google's Gemma terms of use before redistributing it. imagehub does not distribute weights.
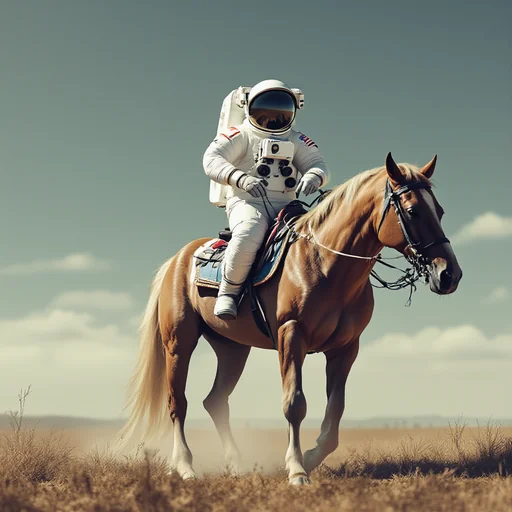
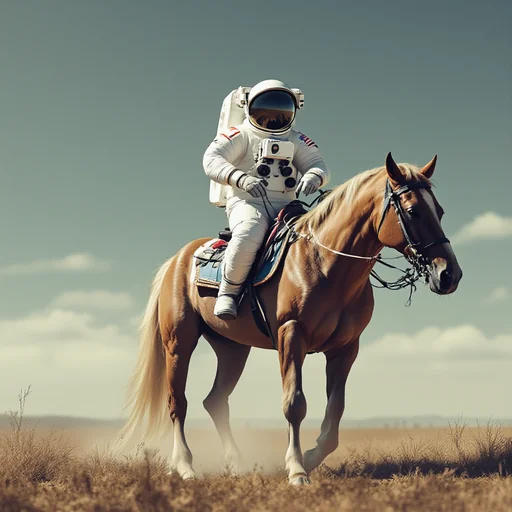
Reference and imagehub, side by side
Drag the slider. Left is the recorded reference, right is imagehub, from the same seed, on CPU in float32.
 referenceimagehub