Kandinsky 2.2
| Model | Source | Revision | Weight license | Parity (CPU, fp32) |
|---|---|---|---|---|
kandinsky-2.2 |
kandinsky-community/kandinsky-2-2-decoder | 9ae140d |
Apache-2.0 | Verified |
Catalog: kandinsky-2 ·
Models: kandinsky-2.2 · Task: t2i
Architecture. A CLIP text model with projection conditions a PriorTransformer, while a CLIP
vision model with projection supplies the zero image embedding for the negative branch. The prior
uses an UnCLIP scheduler with sample prediction and fixed_small_log variance. Its image embedding
conditions a U-Net with ResnetDownsampleBlock2D, SimpleCrossAttn* blocks and scale_shift time
modulation. A MoVQ VQ model with spatially conditioned normalization decodes the latents. The
decoder uses a DDPM scheduler with linear betas and clipping.
Usage.
from imagehub import pipeline

with pipeline(
    "t2i", backend="kandinsky-2.2", model="checkpoints/kandinsky-2.2", device="mps"
) as pipe:
    result = pipe("a cat, oil painting", seed=42)
    result.images[0].save("cat.png")
Settings. The prior defaults to 25 steps and guidance 4.0; the decoder defaults to 100 steps,
guidance 4.0 and 512×512 output. The supported options are steps, guidance, prior_steps,
prior_guidance and negative_prompt. Unrecognized settings raise an error.
Seed compatibility. On CPU, the same seed and settings give the same image as diffusers with
generator=torch.Generator("cpu").manual_seed(seed) (validation). MPS and CUDA
runs are smoke tests only; there is no claim of exact equality on these devices.
Out of scope. Img2img, inpainting, ControlNet, prior interpolation and fp16/bf16 parity are not supported.
License. The decoder and prior weights use the Apache-2.0 license. imagehub does not distribute weights.
Reference and imagehub, side by side
Drag the slider. Left is the recorded reference, right is imagehub, from the same seed, on CPU in float32.
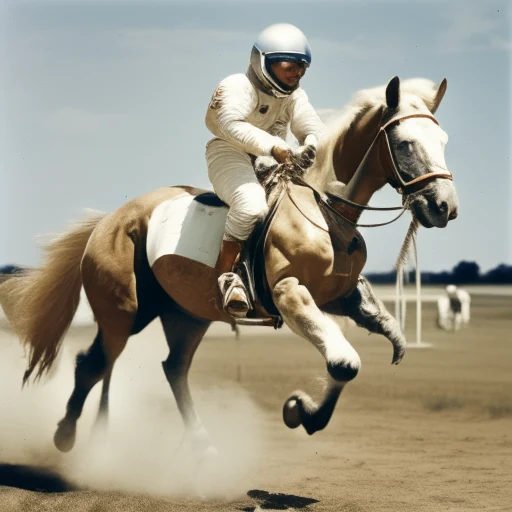
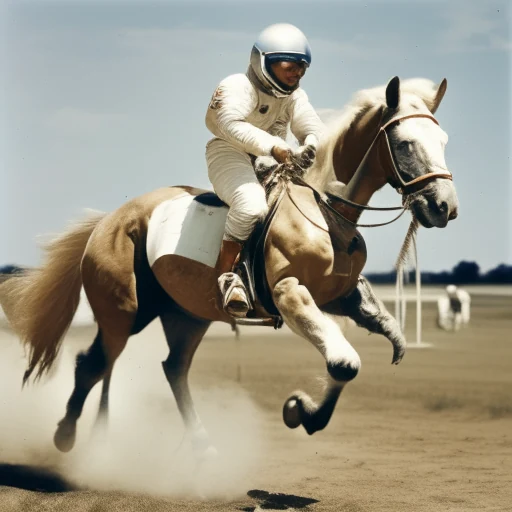 referenceimagehub