FLUX.1
| Model | Source | Revision | Weight license | Parity (CPU, fp32) |
|---|---|---|---|---|
flux1-schnell |
black-forest-labs/FLUX.1-schnell | 741f7c3 |
Apache-2.0 | Verified |
flux1-dev |
black-forest-labs/FLUX.1-dev | 3de623f |
FLUX.1-dev Non-Commercial License | Verified |
flux1-krea-dev |
black-forest-labs/FLUX.1-Krea-dev | 8162a9c |
FLUX.1-dev Non-Commercial License | Verified |
flux-1-lite-8b |
Freepik/flux.1-lite-8B | 16b9373 |
FLUX.1-dev Non-Commercial License | Verified |
flux1-kontext-dev (+ image input) |
black-forest-labs/FLUX.1-Kontext-dev | 24e9ded |
FLUX.1-dev Non-Commercial License | Verified |
Catalog: flux-1 ·
Models: flux1-schnell, flux1-dev, flux1-krea-dev, flux-1-lite-8b, flux1-kontext-dev · Task: t2i
Architecture. CLIP-L supplies a pooled embedding and T5-XXL supplies sequence embeddings to a 12B rectified-flow transformer with 19 double-stream blocks, 38 single-stream blocks, 24 attention heads of width 128 and 3-axis RoPE. The dev checkpoint adds a guidance embedding. A 16-channel VAE with a shift factor decodes latents packed in 2×2 patches. The flow-match Euler scheduler uses a static shift of 1.0 for schnell and dynamic shifting for dev. The native image size is 1024×1024.
Usage. Both repositories are gated. Accept the repository terms and provide HF_TOKEN when
downloading:
from imagehub import pipeline

with pipeline(
    "t2i", backend="flux1-schnell", model="checkpoints/flux1-schnell", device="mps"
) as pipe:
    result = pipe("a cat, oil painting", seed=42)
    result.images[0].save("cat.png")
Settings. Schnell defaults to 4 steps, guidance 0.0 and a maximum sequence length of 256. Dev
defaults to 50 steps, guidance 3.5 and a maximum sequence length of 512. Both default to 1024×1024,
and width/height must be multiples of 16. The other supported options are num_images, seed,
latents, negative_prompt and true_cfg_scale. Unrecognized settings raise an error.
Validation. On CPU, the same seed and settings give the same image as diffusers with
generator=torch.Generator("cpu").manual_seed(seed) (validation). MPS and CUDA
runs are smoke tests only; there is no claim of exact equality on these devices.
Out of scope. Fill, Redux, Depth and Canny variants, ControlNet and fp16/bf16 parity are not
supported. flux1-schnell, flux1-dev, flux1-krea-dev and flux-1-lite-8b take no image
input; for Kontext, see below.
License. The schnell weights use the Apache-2.0 license. The dev, Krea [dev] and Kontext weights use the FLUX.1-dev Non-Commercial License; see the license. imagehub does not distribute weights.
Flux.1-Lite 8B
flux-1-lite-8b (Freepik/flux.1-lite-8B) distills FLUX.1-dev by reducing the double-stream
transformer from 19 blocks to 8 while retaining all 38 single-stream blocks, the two text encoders,
VAE and dynamically shifted flow-match scheduler. The component weights are published only in
bfloat16 and are upcast for CPU float32 inference.
from imagehub import pipeline

with pipeline(
    "t2i", backend="flux-1-lite-8b", model="checkpoints/flux-1-lite-8b", device="mps"
) as pipe:
    result = pipe("a cat, oil painting", seed=42)
    result.images[0].save("cat.png")
- Defaults. 28 steps, guidance 3.5, 512 text tokens and 1024x1024, matching the model card.
- Access and license. The repository is ungated. The weights inherit the FLUX.1-dev Non-Commercial License.
- Memory. The two transformer shards total about 16.3 GB in bfloat16. CPU float32 loading requires roughly twice that for the transformer, plus T5-XXL, CLIP-L and the VAE.
FLUX.1 Krea [dev]
flux1-krea-dev (black-forest-labs/FLUX.1-Krea-dev) is an aesthetics-focused fine-tune of the
FLUX.1 [dev] architecture, per its model card. Its published configs are identical to those of
flux1-dev, so it runs on the same backend, text encoders, transformer and VAE with no new code.
from imagehub import pipeline

with pipeline(
    "t2i", backend="flux1-krea-dev", model="checkpoints/flux1-krea-dev", device="mps"
) as pipe:
    result = pipe("a cat, oil painting", seed=42)
    result.images[0].save("cat.png")
- Defaults. 28 steps (the diffusers
FluxPipelinedefault; the model card gives no step count), guidance 4.5 (the model card),max_sequence_length512 and 1024×1024. The other options are the same as forflux1-dev. - License and access. The repository is gated and the weights use the FLUX.1-dev
Non-Commercial License. Accept the terms and provide
HF_TOKENwhen downloading. - Memory. The same as
flux1-dev: about 47.6 GB for the transformer, 19 GB for T5-XXL, 0.5 GB for CLIP-L and 0.3 GB for the VAE in float32.
FLUX.1 Kontext [dev]
flux1-kontext-dev (black-forest-labs/FLUX.1-Kontext-dev) is the FLUX.1 transformer trained to
edit an image from a text instruction. It shares the FLUX.1 backend, text encoders and VAE; the
only difference is that the tokens of the encoded input image are appended to the sequence, and
only the generated tokens are decoded.
from PIL import Image
from imagehub import pipeline

with pipeline(
    "t2i", backend="flux1-kontext-dev", model="checkpoints/flux1-kontext-dev", device="mps"
) as pipe:
    result = pipe("Add a red hat to the scene", image=Image.open("photo.png"), seed=0)
    result.images[0].save("edited.png")
- The image is optional. Without
image, the model generates from the prompt alone, likeflux1-dev. - Input resizing. The input is converted to RGB (grayscale, RGBA and palette images included), rounded down to a multiple of 16, and then resized to the preferred Kontext resolution whose aspect ratio is closest to its own (672×1568 up to 1568×672, 1024×1024 for a square). It is encoded by the VAE (the mode of the posterior, shifted and scaled) before it joins the sequence.
- Output size. The size of the result comes from
heightandwidth(default 1024×1024), not from the input image. They are rescaled to at mostmax_areapixels (default 1024²) at the same aspect ratio and rounded down to multiples of 16. To keep the input's shape, pass its size asheightandwidth. - Defaults. 28 steps, guidance 3.5,
max_sequence_length512,true_cfg_scale1.0 (no negative prompt). The model card's examples use guidance 2.5; passguidance=2.5to use it. The other FLUX.1 options (num_images,seed,latents,negative_prompt,true_cfg_scale) work as forflux1-dev;max_areais the one added option besidesimage. - License and access. The repository is gated and the weights use the FLUX.1-dev
Non-Commercial License. Accept the terms and provide
HF_TOKENwhen downloading. - Memory. The same as
flux1-dev: about 47.6 GB for the transformer, 19 GB for T5-XXL, 0.5 GB for CLIP-L and 0.3 GB for the VAE in float32. - Limits. One input image only. Inpainting (
FluxKontextInpaintPipeline), several input images, IP-Adapter and fp16/bf16 parity are not supported. - Seed compatibility. On CPU, the same seed, image and settings give the same image as
diffusers 0.40.0
FluxKontextPipeline(validation).
Reference and imagehub, side by side
Drag the slider. Left is the recorded reference, right is imagehub, from the same seed, on CPU in float32.
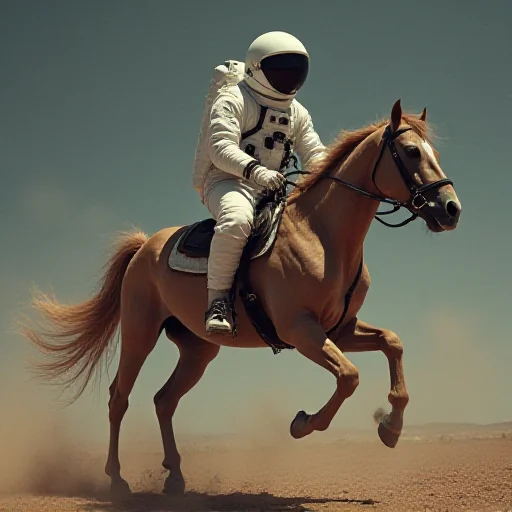
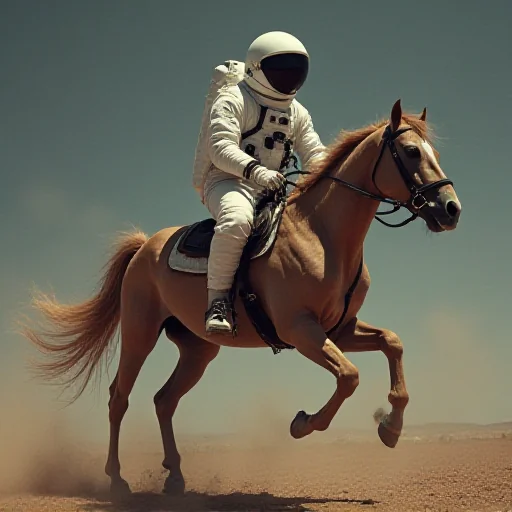 referenceimagehub
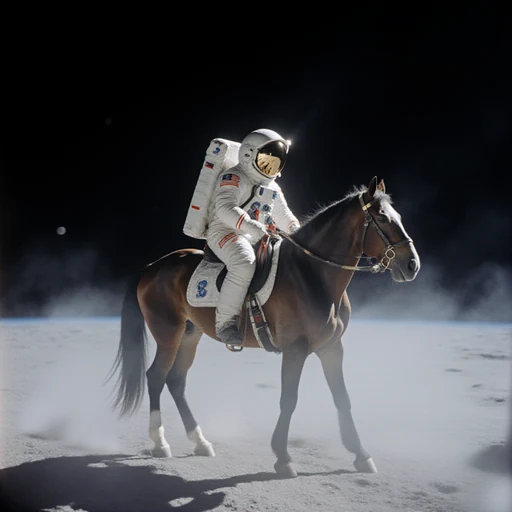
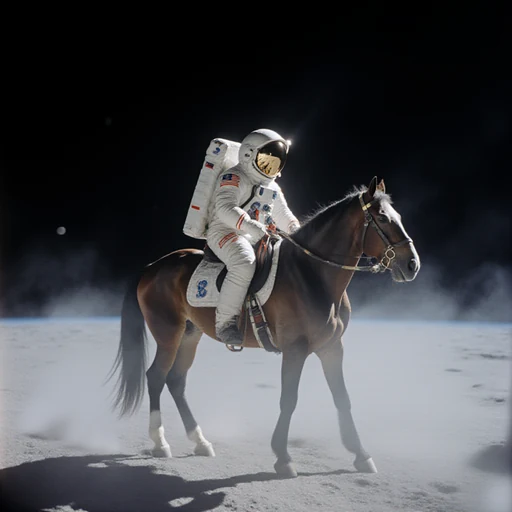 referenceimagehub
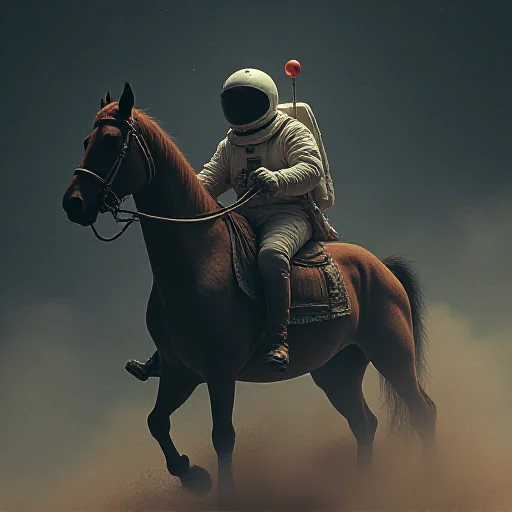
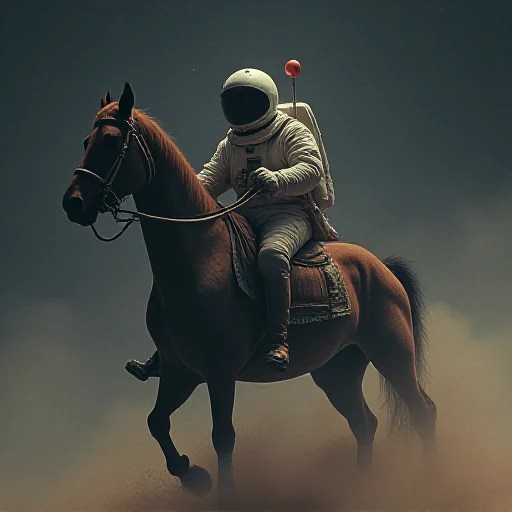 referenceimagehub
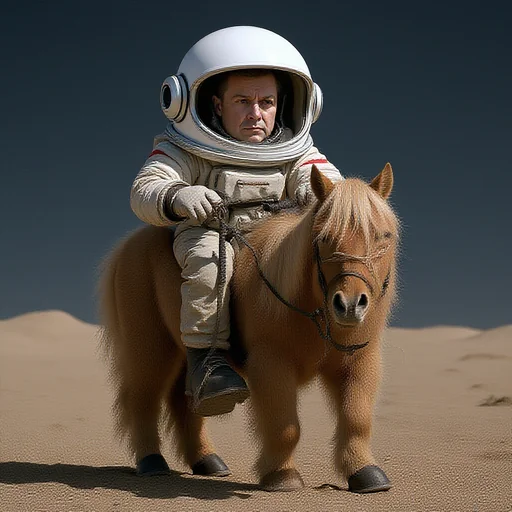
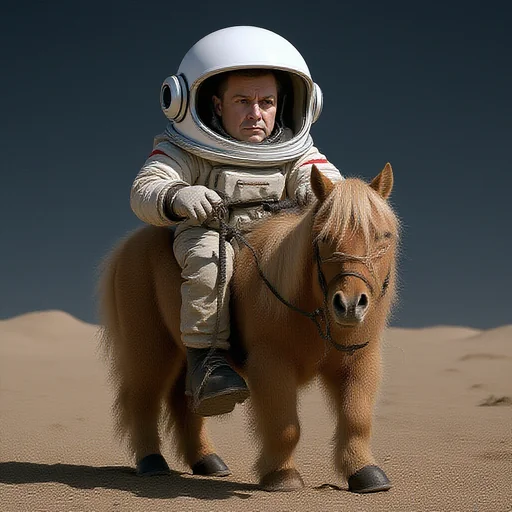 referenceimagehub